Umless
Say it three times. Umless keeps your best take.
LiveNov 2026 → now
Open-source CLI and hosted try are live. In a 60-day revenue sprint (Nov 6 2026 to Jan 5 2027).
What it is
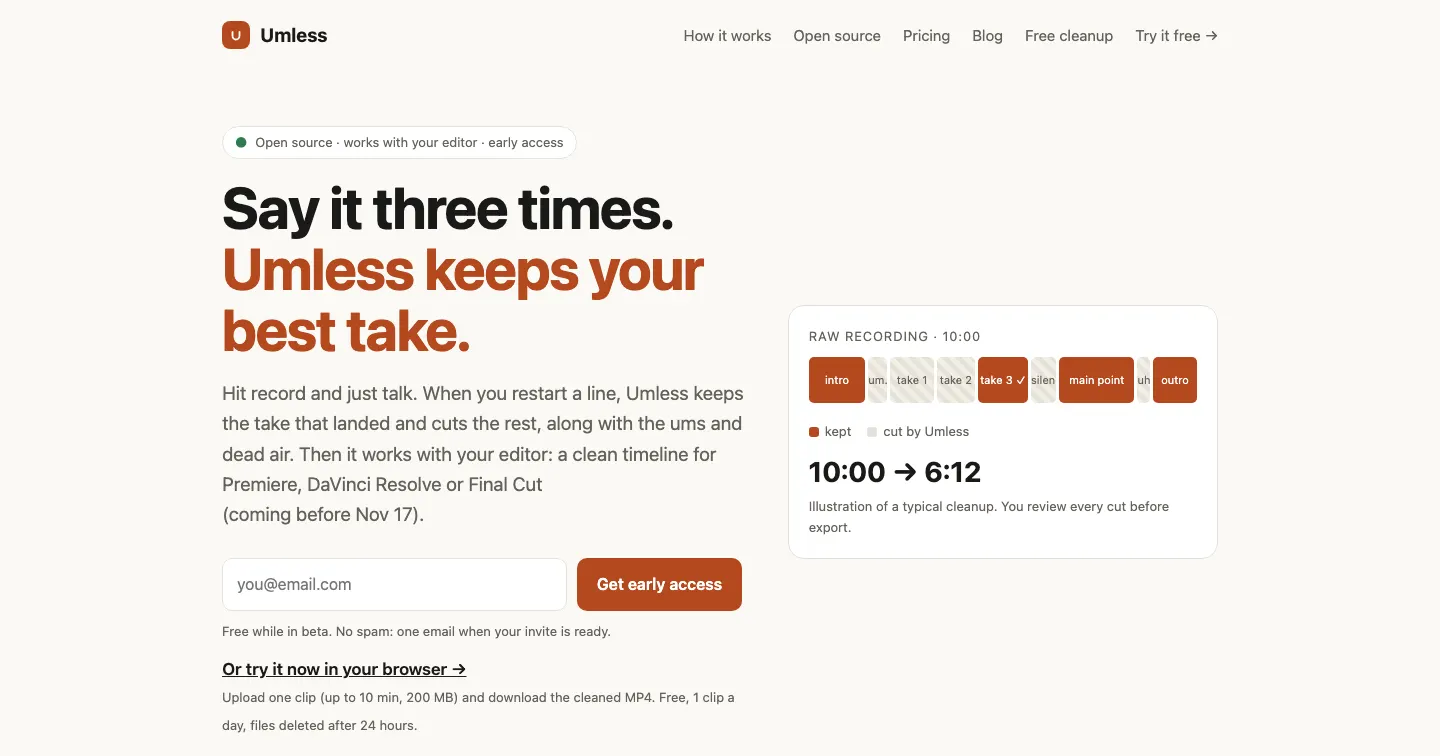
Umless cuts ums, stutters, retakes and dead air out of talking-head video and demo recordings. You hit record, restart a line as many times as you need, and Umless keeps the take that landed. The core is an MIT-licensed CLI. On top of it there is a hosted browser app, an MCP server so Claude or other agents can clean a video, and a Claude Code plugin.
Who it's for
YouTubers, course creators, podcasters and indie founders who record their own demos. Also developers who want an AI agent to do the editing.
What's different
Gling, Descript, TimeBolt, Cleanvoice and AutoCut are closed and charge per minute or by credits. Umless is open, so you can read why every word was cut. It focuses on retakes, not plain silence removal, because silence and um removal are already free inside CapCut and Premiere. In about 10K search phrases about ums and retakes, people named Premiere, CapCut and Resolve far more than any new tool, so the plan is to feed your existing editor, not replace it. Compared to my other products it is the first one that is open source from day one and agent-native from day one.
How it works
ffmpeg pulls the audio. ElevenLabs Scribe v2 transcribes word by word, then a second cheap pass with NVIDIA Parakeet finds the ums Scribe skipped and places each one only inside a real gap in the audio. Rules mark fillers and repeats, and a small GPT model marks retakes and false starts. ffmpeg renders the kept parts, snapping cuts to the quietest 10 ms with short fades. The hosted app is Next.js in Docker on a home Linux laptop behind a Cloudflare tunnel. The landing page is a Cloudflare Worker with D1.
The goal
$2,000 MRR by January 5 2027, with AI agents running most of the go-to-market and me putting in about 30 minutes a day.
The model choice is the product. The transcription model I picked because it supposedly kept every um caught 4% of them on real footage, and it also cut 27 seconds of real speech as dead air. I only found out because I built a labelled test set. On distribution: raw pageviews lied by about 7x (mistake #4 in my article), and the launch copy started claiming features before they shipped, so I added an honesty check before anything gets posted.
Written about in
- X Article #4: A tiny AI lab just beat Grok at running ads. Here's what I'm building because of it. Nov 10, 2026
- X Article #3: I turned 3 old laptops and my phone into one AI team. Here's the setup. Nov 9, 2026
- X Article #2: Apple approved my teleprompter app in 8 hours. An AI submitted my game. 29 cold emails: 0 replies. Nov 8, 2026
- X Article #1: Marketers are now worth more than engineers. I'm an engineer with 6 products and $0. Here's my 6-month plan. Nov 7, 2026
Versions and pivots
2026-11-06
Started as "AudioBet", a research bet on which AI audio product could reach $2k MRR in 60 days. The winner was cleaning up demo videos.
2026-11-06
Narrowed to Umless with an open-core model: free MIT CLI, paid cloud and done-for-you tiers. Public repo created the same day.
2026-11-07
Switched the transcription model after the evaluation (PR #10). Added the MCP server, the Claude skill and npx install (PR #11).
Next
Show HN on Nov 17 2026, 8:30 ET. The 60-day verdict on Jan 5 2027.